Your Rate Limiter Says 10 Per Second. I Measured 20.
Four rate limiting algorithms, one request stream, and a harness that counts what each of them actually admits in the worst rolling second.
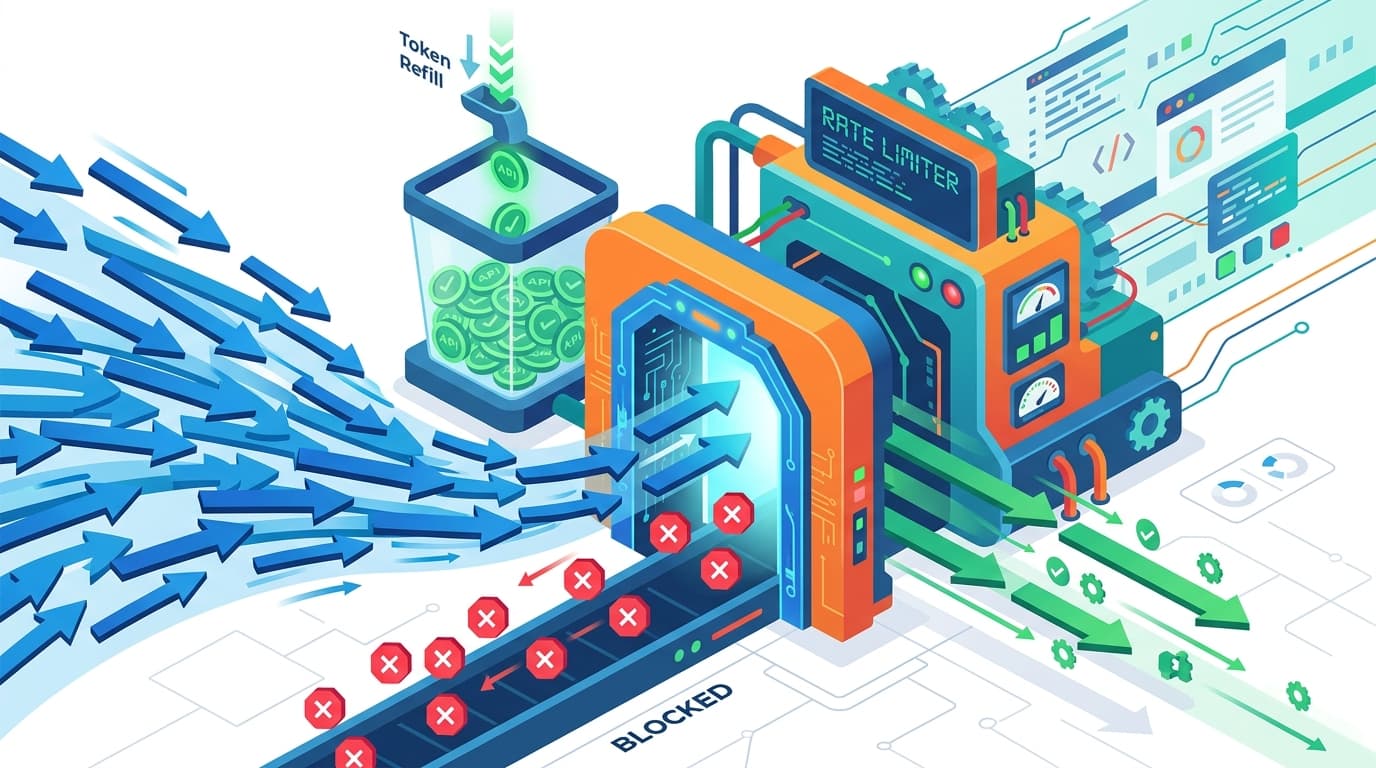
Your Rate Limiter Says 10 Per Second. I Measured 20.
The limit was ten requests per second per API key. The incident graph showed twenty arriving inside one second, all admitted, all from the same key. Nobody had changed the config. The limiter was working exactly as written.
The bug was in what "per second" means. A limiter that counts inside calendar seconds and a limiter that bounds any rolling second are different products, and most rate limiter write-ups quietly swap one for the other. So rather than argue about it, I wrote a harness, pushed the same request stream through four algorithms, and counted what came out the other side.
The measuring stick
A limiter here is a function from a timestamp to a verdict. Nothing else is needed, so one driver can run all four:
const assert = (cond, msg) => { if (!cond) throw new Error(msg); };

function drive(limiter, stream) {
  const admitted = [];
  for (const t of stream) if (limiter(t)) admitted.push(t);
  return admitted;
}

// the maximum admissions inside ANY 1000 ms window, not inside calendar seconds
function peakRate(admitted, windowMs) {
  let peak = 0;
  for (let i = 0; i < admitted.length; i++) {
    let n = 0;
    for (let j = i; j < admitted.length && admitted[j] < admitted[i] + windowMs; j++) n++;
    if (n > peak) peak = n;
  }
  return peak;
}

const LIMIT = 10, WINDOW = 1000;

// A: ten requests just before a window boundary, ten just after
const boundaryBurst = [
  ...Array.from({ length: 10 }, (_, i) => 900 + i * 10),
  ...Array.from({ length: 10 }, (_, i) => 1000 + i * 10),
];
// B: a client that ignores the limit entirely, 30 rps for 10 s
const flood = Array.from({ length: 300 }, (_, i) => Math.round(i * (1000 / 30)));
// C: a well-behaved client sending exactly the limit, 10 rps for 10 s
const compliant = Array.from({ length: 100 }, (_, i) => i * 100);
peakRate is the whole argument. Counting admissions per calendar second flatters
every algorithm in this article; counting the worst rolling second does not.
Fixed window: 20 through a 10 per second limit
function fixedWindow(limit, windowMs) {
  let currentWindow = null, count = 0;
  return (now) => {
    const w = Math.floor(now / windowMs);
    if (w !== currentWindow) { currentWindow = w; count = 0; }
    if (count >= limit) return false;
    count++;
    return true;
  };
}

const fwA = drive(fixedWindow(LIMIT, WINDOW), boundaryBurst);
console.log('fixed window, stream A:', fwA.length, 'admitted, peak', peakRate(fwA, WINDOW));
// fixed window, stream A: 20 admitted, peak 20
Twenty requests, twenty admitted, and twenty of them land inside the 190 ms straddling the boundary. Both calendar seconds are innocent: second 0 saw ten, second 1 saw ten. The rolling second saw double the limit.
On the flood the same limiter looks excellent — 100 of 300 admitted, peak 10 — which is the trap. A limiter can be exactly right about sustained load and wrong by a factor of two about the thing that actually knocks a backend over.
Doubling is the ceiling, not a coincidence. A fixed window grants a fresh limit
at each boundary, so the worst rolling window is two adjacent grants: 2 x limit.
I swept the burst phase across all 1000 offsets in the window and never got past 20.
Sliding log: the only one that held
Keep the timestamps, drop the ones that have aged out, count what is left:
function slidingLog(limit, windowMs) {
  const log = [];
  return (now) => {
    while (log.length && log[0] <= now - windowMs) log.shift();
    if (log.length >= limit) return false;
    log.push(now);
    return true;
  };
}

for (const [name, stream] of [['A', boundaryBurst], ['B', flood], ['C', compliant]]) {
  const adm = drive(slidingLog(LIMIT, WINDOW), stream);
  console.log('sliding log, stream', name + ':', adm.length, 'admitted, peak', peakRate(adm, WINDOW));
}
// sliding log, stream A: 10 admitted, peak 10
// sliding log, stream B: 100 admitted, peak 10
// sliding log, stream C: 100 admitted, peak 10
Peak 10 on every stream, and the compliant client loses nothing. I then swept 600 shaped streams — every silence offset from 0 to 990 ms, crossed with flood rates from 1000 down to 20 rps — looking for any stream that pushed it over. There were none. The sliding log is the definition, so this is less a result than a control.
It bills for that by the entry. At a 10 per second limit it holds ten timestamps per identity; at 10,000 per second it holds ten thousand, roughly 80 KB of timestamps for one key before any container overhead. Multiply by your identity count before you pick this one.
Sliding window counter: a different-shaped hole
The usual patch is to keep two integers instead of a list, and weight the previous window by how much of it still overlaps the rolling window:
function slidingCounter(limit, windowMs) {
  let cur = 0, prev = 0, curWindow = null;
  return (now) => {
    const w = Math.floor(now / windowMs);
    if (curWindow === null) curWindow = w;
    if (w !== curWindow) { prev = (w === curWindow + 1) ? cur : 0; cur = 0; curWindow = w; }
    const overlap = 1 - (now % windowMs) / windowMs;
    if (prev * overlap + cur >= limit) return false;
    cur++;
    return true;
  };
}
On the boundary burst it admits 11 against a limit of 10, which is the number people quote, and it is where most articles stop. The weighting assumes the previous window's requests were spread evenly across it. Build a stream that violates that assumption and the estimate collapses:
// silent until 900 ms, then 500 rps for two seconds
const backLoaded = [];
for (let t = 900; t < 2900; t += 2) backLoaded.push(t);

for (const [name, make] of [['fixed window', () => fixedWindow(LIMIT, WINDOW)],
                            ['sliding log', () => slidingLog(LIMIT, WINDOW)],
                            ['sliding counter', () => slidingCounter(LIMIT, WINDOW)]]) {
  const adm = drive(make(), backLoaded);
  console.log(name.padEnd(16), 'admitted', adm.length, 'peak', peakRate(adm, WINDOW));
}
// fixed window     admitted 30 peak 20
// sliding log      admitted 20 peak 10
// sliding counter  admitted 29 peak 19
Nineteen against a limit of ten. All ten of window 0's grants land in its final 100 ms, so when window 1 opens the counter believes those ten are spread back across a full second and lets the budget out again as the phantom overlap decays. Sweeping the same 600 shaped streams, the counter's worst rolling second is 20 — identical to the fixed window it was introduced to fix.
Across 2000 randomised bursty streams (120 requests each, gaps uniform on 0 to 60 ms, random phase) its peak rolling second exceeded the sliding log's in 2000 of 2000 trials, by a mean of 4.0 requests per second and a worst case of +9. It also errs the other way on throughput: on the compliant client it rejected 5 of 100 requests from a client that never once exceeded the limit.
Two integers instead of a list is a real saving. Getting within one request of exact is not what you bought.
Token bucket, and the dial you are really turning
function tokenBucket(capacity, refillPerSec) {
  let tokens = capacity, last = null;
  return (now) => {
    if (last === null) last = now;
    tokens = Math.min(capacity, tokens + ((now - last) / 1000) * refillPerSec);
    last = now;
    if (tokens < 1) return false;
    tokens -= 1;
    return true;
  };
}

const tbB = drive(tokenBucket(LIMIT, LIMIT), flood);
console.log('token bucket, stream B:', tbB.length, 'admitted, peak', peakRate(tbB, WINDOW));
// token bucket, stream B: 109 admitted, peak 19
Nineteen again, from the algorithm usually presented as the one that gets this right.
It is not a defect. A full bucket plus a second of refill is capacity + rate
admissions, and the measured worst rolling second across the sweep comes out at
rate + capacity - 1 every time:
| capacity (refill 10/s) | worst rolling second | multiple of the limit |
|---|---|---|
| 1 | 10 | 1.0x |
| 2 | 11 | 1.1x |
| 5 | 14 | 1.4x |
| 10 | 19 | 1.9x |
| 20 | 29 | 2.9x |
Burst tolerance and rate accuracy are one dial, not two. Capacity 1 pins the rolling second to exactly the limit and refuses every burst, including the dashboard that fires twenty parallel calls on load. Capacity equal to the rate buys that dashboard and costs you 1.9x. Pick the number you can defend to whoever owns the backend.
A leaky bucket is the same arithmetic read upside down — a level that drains instead of tokens that accumulate — and it measured identically on all four streams: 109 admitted on the flood, peak 19. Where they differ is what happens to the excess: the token bucket rejects it, a leaky-bucket queue holds it and releases at the drain rate, which turns a 429 into latency. That is a product decision, not an algorithmic one.
Everything above assumed one process
Every number so far came from a single limiter holding its own state. Run the same in-memory limiter in each of N processes, round-robin 1000 requests across them in one second, and the 10 per second limit becomes:
| processes | admitted in one second |
|---|---|
| 1 | 10 |
| 2 | 20 |
| 4 | 40 |
| 16 | 160 |
The effective limit is limit x processes, so an autoscaler silently edits your rate
limit. That is why the state moves to Redis, and moving it there introduces the
failure that ruins more limiters than any algorithm choice.
Read, decide, write. With 200 concurrent requests against a limit of 10 and one network round trip between the read and the write:
const store = new Map();
const hop = () => new Promise((r) => setImmediate(r)); // stands in for the round trip

async function readThenWrite(key) {
  const n = store.get(key) ?? 0;
  await hop();
  if (n >= 10) return false;
  store.set(key, n + 1);
  return true;
}

const results = await Promise.all(Array.from({ length: 200 }, () => readThenWrite('k')));
console.log('admitted', results.filter(Boolean).length, 'final counter', store.get('k'));
// admitted 200 final counter 1
Two hundred of two hundred, and the counter finished at 1. It is not lagging, it is being overwritten by whoever writes last. The fix is to stop reading before you decide and let the write itself be the decision:
const atomicStore = new Map();
async function atomicIncr(key) {
  const n = (atomicStore.get(key) ?? 0) + 1; // one indivisible step
  atomicStore.set(key, n);
  await hop();
  return n <= 10;
}
const atomicResults = await Promise.all(Array.from({ length: 200 }, () => atomicIncr('k')));
console.log('admitted', atomicResults.filter(Boolean).length);
// admitted 10

assert(results.filter(Boolean).length === 200, 'read-then-write should over-admit');
assert(atomicResults.filter(Boolean).length === 10, 'atomic path must hold the limit');
console.log('assertions passed');
In Redis that is INCR for a window counter, or a Lua script for anything needing
more than one step. Token bucket needs three reads and two writes, so it needs the
script:
-- KEYS[1] bucket  ARGV: capacity, refillPerSec, nowMs, requested
local capacity = tonumber(ARGV[1])
local refill   = tonumber(ARGV[2])
local now_ms   = tonumber(ARGV[3])
local want     = tonumber(ARGV[4])

local state  = redis.call('HMGET', KEYS[1], 'tokens', 'ts')
local tokens = tonumber(state[1])
local last   = tonumber(state[2])
if tokens == nil then tokens = capacity; last = now_ms end

-- keep the fraction. flooring here throws away every partial token.
tokens = math.min(capacity, tokens + ((now_ms - last) / 1000.0) * refill)

local allowed = 0
if tokens >= want then allowed = 1; tokens = tokens - want end

-- EXPIRE takes an integer. ceil, and outlive a full refill.
redis.call('HSET', KEYS[1], 'tokens', tostring(tokens), 'ts', tostring(now_ms))
redis.call('EXPIRE', KEYS[1], math.ceil(capacity / refill) + 1)

local retry = 0
if allowed == 0 then retry = math.ceil((want - tokens) / refill) end
return { allowed, tostring(tokens), retry }
Two lines in there are scar tissue. Flooring the refill looks harmless and is not: if
you write math.floor(elapsed_ms / 1000 * refill) while still stamping ts = now_ms
every call, a client polling faster than one request per token interval resets the
refill clock before it earns a token. I ran that variant under a Lua interpreter
against a stub Redis — cap 10, refill 5 per second, a client at 50 rps for ten
seconds. It admitted 10 requests out of 500 and then zero, forever. The corrected
script admits 59, which is the expected rate x seconds + capacity - 1. The other
line is EXPIRE: a capacity of 20 over a refill of 3 produces a TTL of 13.33, Redis
answers ERR value is not an integer or out of range, and if your gateway fails open
on script errors you have shipped a limiter that never limits.
Set the TTL inside the same script as the write. An HSET that lands and an EXPIRE
that does not leaves a key with no TTL, and Redis will hold that identity's bucket
until something evicts it.
What the vendors publish
Three public APIs, three sets of documented behaviour that line up with the measurements above.
GitHub's REST API returns x-ratelimit-limit, x-ratelimit-remaining,
x-ratelimit-used and x-ratelimit-reset, documented as the instant the current
window resets, in UTC epoch seconds, with 60 requests per hour unauthenticated and
5,000 for an authenticated user. A single reset instant is
something a window counter has and a continuously refilling bucket does not, so the
headers tell you the shape of the enforcement even though the implementation is not
published. Separately they document a secondary limit of no more than 100 concurrent
requests, which is a concurrency bound rather than a rate at all.
Stripe publishes 100 requests per second per account in live mode, 25 in a sandbox, and says its rate limits "in general reset after one second" — again a reset, not a drain. Their advice for clients is a token bucket, which is the right side of the wire for one: shaping your own outbound traffic is exactly the job a bucket with a tuned capacity does well.
Cloudflare is the most direct about the cost of distribution. Their rate limiting
rules take a period and a requests-per-period, every rule carries the data centre ID
cf.colo.id as a mandatory hidden characteristic, and the docs say counters "are not shared across data
centers" and warn that the rules are not built to admit a precise number of requests
to your origin, with a delay of up to a few seconds between seeing a request and
updating the counters. That is the
multi-process table from earlier, at global scale, documented as intended behaviour.
The clock is also shared state
The harness in this article has one clock, and that is its biggest lie. Every
timestamp came from the same integer sequence, so the four algorithms disagreed only
about arithmetic. Production hands that clock to whichever gateway happens to serve
the request: the Lua script above takes now_ms as an argument, and a gateway whose
clock runs two seconds fast will mint two seconds of tokens for every key it touches.
Reading the clock inside Redis instead moves the problem rather than removing it —
TIME is not replicated, so a failover can walk the clock backwards and the refill
term goes negative.
I did not measure any of that, because I could not build a stream that reproduces it honestly, and a number I cannot regenerate is worse than no number. What I would do before trusting any of the results above in a real system is chart per-gateway clock skew next to the admission counts, and treat a limiter that has never been tested against a skewed clock as untested.
Comments (0)
No comments yet. Be the first to share your thoughts!
Related Articles